This is the fourth article in a series looking at migrating from Jadu into LocalGov Drupal (LGD) for the Central Bedfordshire site. In the first article we looked at the Jadu API itself and setting things up so that we could make calls to the API and parse the XML data using the migration systems available.
In the second article we looked at reproducing Jadu URLs to create redirects for migrated content, even though the Jadu API doesn't contain any URL information.
In the third article we looked at a more complex example of migration, taking documents and pages from Jadu and creating a guide pages from that data.
Now it is time to move onto what became the most complex part of the Central Bedfordshire migration, which was moving directories data from Jadu to LGD. Directories were used on the Jadu site to store all sorts of information, which included schools, the location of car parks, contact information of homecare providers, and even an a-to-z glossary of recycling. This data served different purposes on the site, but it was all hand created and important to bring across during the migration work.
In this article we will look at the Jadu data we needed to fetch to find directory information, and how that data was injected into the LGD structure available.
First, let's look at how we get directory information out of Jadu.
Jadu Directories API
Directories in Jadu can be fetched using the directories index at the following endpoint.
https://[domain]/api/directories/all.xml
This returns a list of all the Directories available, which is useful information, but not something we used in this project. Instead, we used this information to address each directory in turn, starting with the directory structure endpoint as the index reference for the directories on the site. The following will call that enpoint for the directory ID of "1".
https://[domain]/api/directories/1.xml
Calling this endpoint returns an XML document that looks like this.
<?xml version="1.0" encoding="utf-8"?>
<directory id="2" entries="3" public_submission="1">
    <name>Directory Name</name>
    <content><![CDATA[Directory page content.]]></content>
    <categories>
        <category id="20000" name="Category One"/>
    </categories>
    <directoryCategories>
        <directoryCategory id="2" name="Category B"/>
        <directoryCategory id="4" name="Category D"/>
    </directoryCategories>
    <fields>
        <field id="1" name="Care Centre" type="text" mandatory="0"/>
        <field id="2" name="Type of Care" type="text" mandatory="0"/>
        <field id="3" name="Care Centre Contact" type="text" mandatory="0"/>
        <field id="4" name="Care Centre picture" type="text" mandatory="0"/>
        <field id="5" name="Our Address" type="text" mandatory="0"/>
        <field id="6" name="Postcode" type="text" mandatory="0"/>
        <field id="7" name="Web address" type="text" mandatory="0"/>
        <field id="8" name="Telephone number" type="text" mandatory="0"/>
        <field id="9" name="Fax number" type="text" mandatory="0"/>
        <field id="10" name="Email" type="text" mandatory="0"/>
        <field id="11" name="Google Map" type="text" mandatory="0"/>
        <field id="12" name="How to find us" type="text" mandatory="0"/>
        <field id="13" name="NHS" type="text" mandatory="0"/>
        <field id="14" name="Care Centre Grade" type="text" mandatory="0"/>
    </fields>
</directory>
We get the title, some small amount of content, and the categorisation of the directory here. We also get a list of fields associated with the directory; with the id, name, type, and mandatory status of each field.
Although this tells us about what sort of data is in the directory, we need to make an additional query to find the directory contents. To do this we need to call the directory entries API endpoint, which has the following path, assuming we are asking for the entries for directory "1".
https://[domain]/api/directories/1/entries.xml
This will return a paginated dataset that looks something like the following.
<?xml version="1.0" encoding="utf-8"?>
<entries directory_id="1" page="1" pages="1" per_page="10" total="1">
    <entry id="3">
        <title>Directory Entry</title>
        <date>1749726040</date>
        <fields>
            <field id="1" name="Care Centre" type="text" displayTitle="true">Test</field>
            <field id="10" name="Email" type="text" displayTitle="true">example@example.com</field>
        </fields>
    </entry>
</entries>
This gives us the title of the directory entry, an undocumented date (which we found to be the creation date) and a number of field entries containing data. This field data uses the field information defined in the directory entry to define content for those fields, but not all fields will be present in this list.
It should be noted that it is also possible to get the data for a single entry in the directory, but the entries endpoint used here gives us the data we are after.
Putting this together we can therefore fetch a directory index page, and use the directory index to find all of the entries for that directory.
LGD Directories Or Publications?
The directory system that Central Bedfordshire used in Jadu has been used to store all sorts of information. As a result, most of the data was fragmented into different needs with different fields and field types used across the structure of the system. You can think of directories in Jadu like content types in Drupal, with each one containing fields associated with that content type. Each directory, therefore, needed to be treated on an individual basis to extract the relevant information into one or two content types in Drupal. First though, we had to do some work to see where each directory fitted into the new site.
The simplest sort of directory to migrate where those directories used for pure content, like the recycling glossary. These were migrated into the LGD Publications system, which uses the book module to collect together groups of pages into a single section. It was fairly easy to migrate the directory entries into publications by using the same techniques that we used in the guide pages migration that we looked at in part 3.
Full Directories in LGD are created using a combination of a central Directory Channel (localgov_directory) content type that contain a number of different content types connected, all of which is fully configurable. Two content types that come with LGD and are of interest to us here are Directory Venue (localgov_directories_venue) and Directory Page (localgov_publication_page). Venue directories are those items that have address information that can be geocoded, Page directories do not have geocoded information but are still structured in a directory format. Build into the directory system in LGD is the concept of facets and searching, which can be easily configured through the site admin interface.
There are therefore a few options to pick from when migrating content from Jadu. The decision as to which to go for each directory is based on the results of the following points:
- How many fields are present in the Jadu directory. If there is only one text field then it doesn't make sense to create a full, faceted, directory for this, so a publication is used.
- If the Jadu directory has more fields, but contains pure information or only content (eg. A to Z of Recycling) then this is created as a publication.
- The type of data available in the fields is useful information also. If the fields look like they need to be searched for can be filtered by one of the fields (as a facet) then this is created as a directory.
- If the Jadu directory contains any sort of address or location information then a directory migration is done using the Venue page content type to create mapping information.
- The quality of the data available needs to be taken into account. If the field contains address information, but the geocoding system won't be able to process that address with any confidence, then the page is created as a directory item of the "Page" type.
- If the Jadu directory contains only a few entries (less than 5) then a publication is created. This is mainly to reduce the overhead that a directory system would bring when there are only a handful of items present. These items can be easily moved into the directory system at a later date, if requried.
Using these rules we then went through all of the directories in Jadu (around 65) to decide on their fate. Each field in that directory then needed to be documented to show if it needed a facet creating for it, or if it could be geolocated into an address. It wasn't just a case of looking at the datatype of the field, but looking at the data it contained to try and approximate if it could be geocoded or even made sense as a facet. This meant a fair amount of time looking at the XML feeds from Jadu and inspecting the data available.
Where the data didn't fit into geocoding or facets it was then saved into the body copy of the directory entry, allowing the data to exist in some format. In a couple of special instances we created fields for this data to ensure it was captured. It was decided to collect anything that didn't fit into fields into the body field to reduce the complexity of the directory content in general. Most directory content in Jadu had multiple fields that weren't used for faceting or searching at all so it made sense to use them as content.
This investigation into directories, as you might imagine, created a pretty large document. It was absolutely necessary to document all of this so that it was clear what data was going where and what it was being used for in the migration.
For the purposes of this article I will look at just migrating data from Jadu into a directory using the Venue content type, mainly to show the geocoding features in action. I've picked the Register of park home licences, since it's pretty innocuous and shows the process well.
Directory Channel Migration
Before we can migrate the content of a directory we need to migrate the main directory page. To do this we set up a migration for the single directory page that takes the content from the directories endpoint in Jadu and creates a Directory Channel content item using that data.
Just like the guide pages migration, we inject the document ID we need to fetch into the migration system, but in this instance we hard code the document_id value of 77 into the migration document. so there is no need to inject it artificially.
source
  ...
  document_id: 77
  urls:
    - 'https://www.centralbedfordshire.gov.uk/api/directories/[DOCUMENT_ID].xml'
  ...
The processing of the directory item is pretty standard, with the content of the directory goes into the content type fields in Drupal.
process:
  # Skip directory entries with an ID of -1.
  id:
    - plugin: skip_on_value
      source: id
      method: row
      value: "-1"
  type:
    plugin: default_value
    default_value: localgov_directory
  title: title
  body/0/format:
    plugin: default_value
    default_value: 'wysiwyg'
  body/0/value: content
  localgov_directory_channel_types:
    - plugin: default_value
      default_value: 'localgov_directories_venue'
  status:
    plugin: default_value
    default_value: 1
  uid:
    plugin: default_value
    default_value: 1
  path/pathauto:
    plugin: default_value
    default_value: 1
The necessity to skip the data if the id value is "-1" comes from a situation we encountered in the project that caused errors in the migration. After setting everything up we found that some requests to the Jadu api would come back with a 200 response code, but contain a blank document with the ID of "-1". It turned out that a decision had been made to unpublish some of the directories, but that information wasn't passed on to the developers on the project. Even though the content was unpublished, Jadu would simply return an incorrect response status code and cause the system to break. On the off-chance that this happened again I added that clause to every directory migration to prevent this causing problems.
Finally, the destination of the migration is just the node entity type, with content type already being set in the processing step above.
destination:
  plugin: 'entity:node'
We now have a central directory page that is ready to accept directory content pages, so let's build that now.
Directory Content Migration
The directory content migration starts off in much the same way as the main directory page migration in that we hard code the document ID into the migration script. We use the same directory ID as the main directory page since they are the same in Jadu.
source:
  ...
  document_id: 77
  urls:
    - 'https://www.centralbedfordshire.gov.uk/api/directories/[DOCUMENT_ID]/entries.xml'
  ..
The migrated directory content items have two IDs associated with them; the ID of the page itself, and the ID of the parent directory page. By updating the source information we can inform the migration system about this so that both IDs can be tracked by the migration mapping system.
source:
  ...
  ids:
    document_id:
      type: integer
    id:
      type: integer
The processing section of the directory pages is fairly sparse in the migration script, but we can assign the certain core fields easily enough. By using the migration_lookup plugin we can convert the parent Jadu directory ID into the Drupal ID that exists on the system. We can also set up dependencies to ensure that the parent migration is run before this one.
process:
  type:
    plugin: default_value
    default_value: localgov_directories_venue
  title: title
  body/0/format:
    plugin: default_value
    default_value: "wysiwyg"
  localgov_directory_channels:
    - plugin: migration_lookup
      migration: directory_park_home_licences
      no_stub: true
      source: document_id
  created: date
  changed: date
  status:
    plugin: default_value
    default_value: 1
  uid:
    plugin: default_value
    default_value: 1
  path/pathauto:
    plugin: default_value
    default_value: 1
This is clearly only a small part of the work we need to do here, we still have all of the directory fields to migrate. As the fields are highly dynamic we can't add them to this migration script and so need to find an alternate mechanism.
To do this I created an event subscriber that triggered on the MigrateEvents::PRE_ROW_SAVE event, which was then used to populate the row being migrated with the fields from the Jadu data. Rather than create 65+ different event subscribers containing masses of duplicate code I instead created a single, abstract, event subscriber class that contained almost all of the logic needed to create the facets, populate the body copy, create geocoding information, or anything else that needed to happen. Each directory extended this class and filled in details on the migration required using a number of constant overrides.
Before running the code that generates the row we double check that the current migration is the one that matches the migration in the sub class. This means that only the directory migrations will run the field creation logic, rather than every migration attempting to import field content.
Here is the setup of the abstract event subscriber.
abstract class AbstractDirectoryEventSubscriber {

  public function __construct(
    protected EntityTypeManagerInterface $entityTypeManager,
    protected AliasRedirectInterface $aliasRedirect,
    protected FixMarkup $fixMarkupService,
    protected GeocoderInterface $geocoder,
    protected WktGeneratorInterface $geoFieldWktGenerator,
    protected DownloadFileInterface $downloadFile,
  ) {}

  public static function getSubscribedEvents(): array {
    $events[MigrateEvents::PRE_ROW_SAVE][] = ['onMigratePreRowSave'];
    return $events;
  }

  public function onMigratePreRowSave(MigratePreRowSaveEvent $event): void {
    $migrationId = $event->getMigration()->getBaseId();

    if ($migrationId !== static::MIGRATION_NAME) {
      return;
    }

    $this->directoryRowCreate($event);
  }
}
The directoryRowCreate() method run in the event trigger is quite long, so I won't post it in full here, but this is where the field translation happens. The main parts of the method are extracting the fields from the migration data, performing operations on that data, and then writing that data into the destination row, much like the following outline of the method.
protected function directoryRowCreate(MigratePreRowSaveEvent $event): void {
  $fields = $row->getSourceProperty('fields');
  $body = '';

  foreach ($fields as $field) {
    // Extract data from fields.
  }

  // Finished the loop, now set the destination properties, if they are set.
  if ($body !== '') {
    $row->setDestinationProperty('body/0/value', $body);
  }

  // And so on...
}
The MIGRATION_NAME constant in the AbstractDirectoryEventSubscriber class is just one of a set of constants that each subclass can define to control how the directory migration will populate the directory fields. As this is fundamental to how this code works I thought going through these constants is more important, and I can add examples of what is going on in for each constant.
These constants are as follows.
MIGRATION_NAME
The name of the current migration being run, used to check that this is a directory migration.
public const string MIGRATION_NAME = 'directory_content_park_home_licences';
This constant was also used to provide logging context to show what migration was being run.
FACETS_IDS
A list of the fields used to generate facets for the directory. For example, the following would set the field 234 (the "Licence type" field) to be a facet in the following way.
  public const array FACETS_IDS = [
    '234' => 'Licence type',
  ];
This has the effect of first setting up the needed facet entities required to integrate facets into directories and then adding the first data item. To create a facet in LGD we need to generate a facet type entity with an ID (generated from the label of the field) and the label itself.
$facetType = LocalgovDirectoriesFacetsType::create([
  'id' => $facetTypeId,
  'label' => $facetTypeLabel,
]);
$facetType->save();
With this in hand we can then create the facet value for the item in question, using the value of the field from the migration data.
$facetProperties = [
  'bundle' => $facetType->id(),
  'title' => $facetValue,
];
$facets[] = LocalgovDirectoriesFacets::create($facetProperties);
Once the facets are created we then add them to the row in the migration.
$row->setDestinationProperty('localgov_directory_facets_select', $facets);
This will allow the migration handler to link everything up and save the directory content item with a facet.
ADDRESS_IDS
Fields used to generate address information and used to geolocate the location. Jadu has a collection of fields that we can use to convert into an address entity in Drupal.
  public const array ADDRESS_IDS = [
    '316' => 'Address',
    '318' => 'Town or village',
    '319' => 'Postcode',
    '320' => 'County',
  ];
Saving the address information takes a little bit of work, and took me a little while to figure out. What we need to do first is geocode the address using one of the geocode providers that are available in the system. The process of geocoding is to convert an address into coordinates that can be added to a map. These geocode providers are setup when installing LGD, but are part of the Geocoder module. I created a small method in the abstract class to handle the loading of these geocoders.
  public function getGeocoderProviders() {
    if (count($this->geocoderProviders) > 0) {
      return $this->geocoderProviders;
    }

    $providers = [
      'geo_entity_demo_photon',
      'geo_entity_osm',
    ];

    foreach ($providers as $provider) {
      $provider = GeocoderProvider::load($provider);
      if ($provider instanceof GeocoderProviderInterface) {
        $this->geocoderProviders[] = $provider;
      }
    }

    return $this->geocoderProviders;
  }
With this method we can look at geocoding the address information we pulled together from the address fields in Jadu.
/** @var \Geocoder\Model\AddressCollection|null $geocode */
$geocode = $this->geocoder->geocode(implode(', ', $addressInformation), $this->getGeocoderProviders());

// Grab the first result from the geocode results.
$geocode = $geocode->first();
$point = $this->geoFieldWktGenerator->WktBuildPoint($geocode->getCoordinates()->toArray());
If the address can't be geocoded then we the $point variable will be NULL, which is acceptable to save to the database. We would rather have a geocoded address though as this makes for a much more useful interface. Using the information we have obtained from the address fields and the geocoding process we create a GeoEntity object.
$geoEntity = GeoEntity::create([
  'bundle' => 'address',
  'label' => $rowTitle,
  'status' => 1,
  'postal_address' => $addressInformation,
  'location' => $point,
  'accessibility' => [
    'value' => $addressString,
    'format' => 'plain_text',
  ],
]);
$geoEntity->save();
This object is then passed to the location field in the current row of the migration.
$row->setDestinationProperty('localgov_location', $geoEntity);
This links the address to the content item and allows us to pinpoint the item on a map, or to use proximity searches to find the closest points to a location.
ADDRESS_HTML_IDS
This denotes any fields that are stored as HTML in the collection of fields. We then attempt to extract useful information from this string and store that data as an address entity in Drupal.
  public const array ADDRESS_HTML_IDS = [
    '544' => 'Site address',
  ];
As you might imagine, extracting the address from a single HTML string can be difficult. In this case, however, the HTML address was generally structured enough to extract the needed address fields from the data. I did write a few tests for this to make sure that all edge cases encountered were correctly extracted. Out of many thousands of items of content I only saw problems with a handful of addresses, and those issues were easy to spot and add fixes for.
Once we have the address information we can perform the same mechanism as the geocoding address system for the ADDRESS_IDS constant.
SKIP_FIELDS
Fields that are present in Jadu, but shouldn't be present in Drupal are added to this list.
  public const array SKIP_FIELDS = [
    '491' => 'Map',
  ];
This is useful as some fields couldn't be migrated into content, or were not required at all.
Other Fields And The Final Class
All other fields encountered in the data are added to the body copy of the directory page in a structured way, with the labels of the field becoming headings in the directory content. The fact that each field also contained a data type is useful here as we can format the data in the appropriate way. Meaning that email fields were turned into mailto: links, plain text fields were wrapped in HTML tags, and so on.
For the Register of park home licences migration we created a subclass of the AbstractDirectoryEventSubscriber called ParkHomeLicencesMigrationEventSubscriber, along with the constant overrides that are required to migrate this directory content. Here is the class used for the Park home licences migration in full.
class ParkHomeLicencesMigrationEventSubscriber extends AbstractDirectoryEventSubscriber implements EventSubscriberInterface {

  /**
   * Fields that are used to create facets.
   */
  public const array FACETS_IDS = [
    '547' => 'Type of licence',
    '548' => 'Copy of site rules?',
  ];

  /**
   * Fields that are used to create address information from HTML.
   */
  public const array ADDRESS_HTML_IDS = [
    '544' => 'Site address',
  ];

  /**
   * The name of the migration.
   */
  public const string MIGRATION_NAME = 'directory_content_park_home_licences';

}
This shows that we are creating two facets for the Type of licence and the Copy of site rules. During the inspection of direcfory content I found that there were only three values for each of these fields, so faceting them made a lot of sense as it would allow those items to become useful filters. The address information was extracted out of the HTML field called Site address.
Whilst we have abstracted the complexity of the migration out of this class, we still need to register it with Drupal as an event subscriber. As such, we need to add the following to the module's *.services.yml file.
  jadu_migrate_directories_park_home_licences_migration_subscriber:
    class: Drupal\jadu_migrate_directories\EventSubscriber\ParkHomeLicencesMigrationEventSubscriber
    arguments: ['@entity_type.manager', '@jadu_migrate_alias_redirect', '@jadu_migrate_fix_markup', '@geocoder', '@geofield.wkt_generator', '@jadu_migrate_download_file' ]
    tags:
      - { name: 'event_subscriber' }
There's a few different services being injected here, some of these are custom services for this migration, but all of which are used in the processing of fields.
Running The Migration
To run the Register of park home licences migration we just need to run the directory_content_park_home_licences migration with the execute dependencies flag.
drush migrate:import directory_content_park_home_licences --execute-dependencies
This will look at the content migration, see that it has a dependency on the main directory_park_home_licences migration (due to the lookup and the migration dependency) and run that migration first. That action will create the main directory page before creating the directory content pages in this migration so that they can be attached to the main directory page.
Each of the directory migrations is tagged with the tag directories, which meant that they could all be run using a single command.
drush migrate:import --tag=directories --execute-dependencies
Every migration in the Jadu migration is also tagged with jadu, which also meant that everything from start to finish could be run with a single command.
Templates
So, you might be asking, with 65+ directories to migrate did I sit here and hand code every single class? Certainly not! That would be absolutely crazy!
Instead, I created a number of templates that used a simple PHP script to generate the relevant classes and configuration files. All I needed to do was create the correct type of directory using the script before editing the classes to update the relevant fields (if that was even required).
I won't post the entire script here as it is fairly long (and not that interesting) but the main parts look a little like the following.
$machineName = $argv[1];

$sourceDir = __DIR__ . '/templates';
$targetDir = realpath(__DIR__ . '/../');

$directoryFileContent = file_get_contents($sourceDir . '/migrate_plus.migration.directory_xxx.yml');

$directoryFileContent = str_replace('xxx', $machineName, $directoryFileContent);
$directoryContentFileContent = str_replace('xxx', $machineName, $directoryContentFileContent);

$directoryFileTarget = $targetDir . '/config/optional/migrate_plus.migration.directory_' . $machineName . '.yml';

file_put_contents($directoryFileTarget, $directoryFileContent);
In the script, we are taking the first input from the command line and replacing that value anywhere it is found in the template directory migration file. The resulting string is then written to the configuration directory where it can be used straight away in the migration. There are more parts to the script for creating the content migration configuration, the event subscriber class, and the entry in the *.services.yml file.
To run the script, I just went to the directory that contained the scripts (inside the directory migration module) and ran it in the following way.
php ./scripts/migrate_directory_scaffold.php directory_park_home_licences 77 ParkHomeLicencesMigrationEventSubscriber
All I did then was work through the needed migrations, creating each one in turn in about 3 minutes, using the documentation I had previously prepared.
Conclusion
The directories migration consisted of about 60 directories and 18,500 individual directory entries. This all took around 90 minutes to complete.
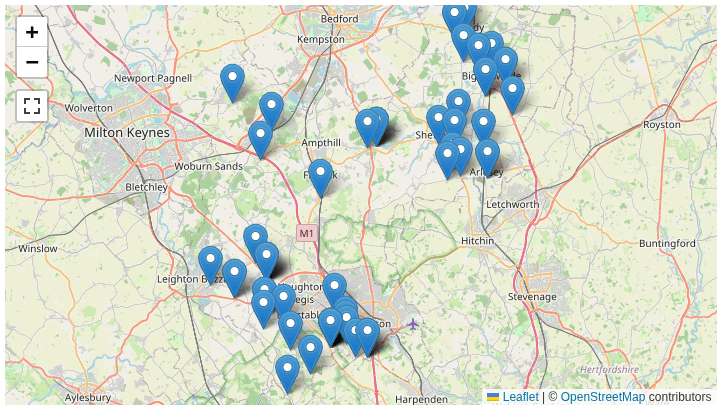
Geocoding addresses from data, sometimes just HTML strings, was interesting. Although the challenge actually came from figuring out how the Geocoder Drupal module geocoded address and how that fit into what the directory system needed. For the Register of park home licences migration we generated the following map from the data in that directory.
Planning migrations is always useful, but it was especially important in this case. We really needed to know exactly what the data looked like and where it was going before we touched any of the migration code. Once I had that list at hand there were only a few unexpected things (like unexpected content in fields or Jadu returning -1 directory IDs) that needed some small workarounds.
Testing was also key to this process. By setting up tests for all of the data extraction systems (some of which were in different services) I could ensure that any deviations of content could be accounted for through a test before changing the code. This meant that I didn't change the code and break the migration for items that were working previously. Having these tests running saved quite a lot of time.
I will release the source code for this migration in the coming weeks. As I write these articles I am tidying things up so that the module can be released as a self contained Jadu to LGD migration starter module. There is some custom logic for Central Bedfordshire that might not be useful for everyone so I'm working on either removing that or creating configuration to allow those customisations to be configured.
If you are looking to migrate from Jadu, or are trying to get to grips with the migration system then please get in touch!
Add new comment